
General Compute signs multi-year agreement with Cerebras
Why the deal matters – beyond the press release General Compute is positioning itself as a middle‑man, buying Cerebras wafer‑scale chips and leasing the speed to customers who can’t afford a balance‑sheet purchase.
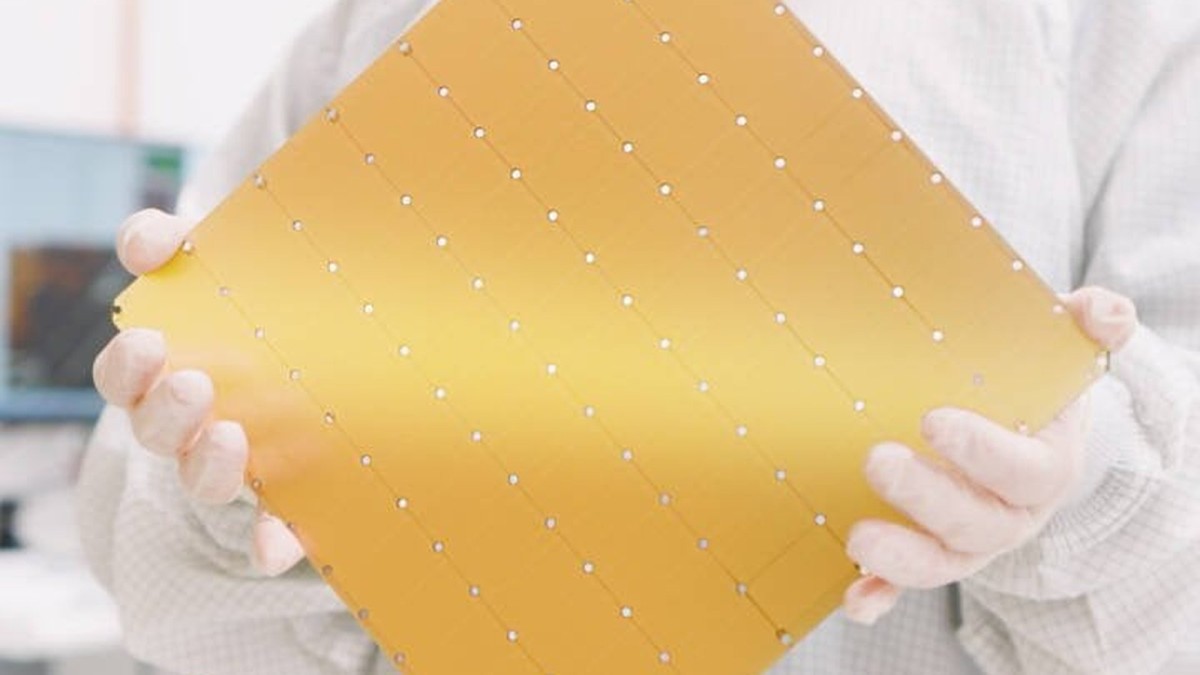
General Compute’s fresh multi‑year pact with Cerebras is the latest flash‑in‑the‑pan headline that makes the VC‑funded hype train look shiny, but the real story is what it means for independent hosting providers trying to stay afloat in a market dominated by hyperscalers and a growing zoo of AI hardware.
Why the deal matters – beyond the press release
General Compute is positioning itself as a middle‑man, buying Cerebras wafer‑scale chips and leasing the speed to customers who can’t afford a balance‑sheet purchase. The company says this is its “largest single hardware commitment” and the first since it secured $400 million in debt financing in July 2026. The lack of disclosed monetary value or deployment scale is typical of these deals – the hype is the headline, the economics stay hidden.
From a founder’s perspective, the move underscores a growing trend: startups are bundling exotic AI silicon with cloud services to create a “speed‑as‑a‑service” offering. It’s a clever way to monetize premium hardware without the capital outlay, but it also adds a layer of cost and complexity that most independent providers will struggle to match.
The hardware mix – a recipe for risk
General Compute isn’t putting all its eggs in the Cerebras basket. The LinkedIn post from CEO Finn Puklowski reveals they will also use Nvidia GPUs for prefill, AMD MI300X cards for the bulk of inference, and SambaNova GN50 chips for decoding. This multi‑vendor approach sounds like a hedge, but in practice it creates a tangled stack of drivers, firmware, and support contracts that can bite you hard when a single component fails.
Running wafer‑scale chips alongside conventional GPUs and AMD cards means you need a data centre that can handle vastly different power and cooling profiles. The whitepaper from May 2026 mentions “options on 15 megawatts of air‑cooled power” at existing colocation sites – a sizable footprint, but still a far cry from the megawatt‑scale deployments that hyperscalers can spin up in weeks. Independent operators must ask: can we actually provision the power and cooling headroom without blowing our capex?
Cost dynamics – the “intelligence per dollar” claim
Puklowski’s brag about “more intelligence per dollar” hinges on using Nvidia for prefill to cut inference costs. The logic is sound: offload the heavy lifting to cheaper GPUs, then hand off the final pass to the ultra‑fast Cerebras engine. But the math is hidden. Nvidia GPUs, especially the latest generations, still command premium pricing, and the integration overhead of juggling three hardware families can erode the projected savings.
For a small‑to‑mid‑size hosting provider, the reality is that each extra hardware vendor adds licensing, support, and staffing costs. You end up with a higher total cost of ownership (TCO) than the headline “cheaper inference” suggests. The risk is that you’ll be selling a service that looks attractive on paper but delivers thin margins once you factor in electricity, cooling, and staff time to keep the stack humming.
Scale vs. agility – the 100 MW rival
The article notes that Cerebras also signed a deal with Gimlet Cloud for 100 MW of wafer‑scale compute. That’s an order of magnitude larger than General Compute’s “options on 15 MW”. Gimlet’s massive power commitment signals that the biggest players are moving straight to hyperscale deployments, where you can amortise the hardware cost across thousands of customers.
Independent providers simply can’t compete on that scale. The lesson is clear: if you’re not building a data centre that can host dozens of megawatts, you either need to niche down on workloads that truly need wafer‑scale speed or pivot to a different value proposition altogether.
The timing – Q1 2027 rollout
General Compute plans to launch Cerebras access in Q1 2027. That gives a narrow window for providers to evaluate the technology, test integration, and decide whether to partner or stay out. The timeline is aggressive; integrating wafer‑scale hardware into an existing cloud stack typically takes months of engineering, not weeks.
From a risk‑management angle, the short lead‑time means you either have a team that can move at startup speed or you’ll be left watching the rollout from the sidelines. Most independent hosting outfits operate on longer procurement cycles, so the pressure to accelerate could force shortcuts that jeopardise reliability.
Business‑risk lens – what founders should watch
The core business risk here is over‑reliance on a single, exotic hardware vendor. Cerebras’ wafer‑scale chips are impressive, but they’re still a niche product with limited supply chains. Any disruption – a fab issue, a firmware bug, or a shipping delay – can cripple your service offering. Diversifying across Nvidia, AMD, and SambaNova mitigates that, but also multiplies the operational overhead.
Another risk is the debt financing that underpins General Compute’s purchase power. While $400 million in debt can fund aggressive expansion, it also means the company must hit revenue targets quickly or risk default. If the market for “Cerebras‑speed inference” doesn’t materialise as projected, the whole stack could become a stranded asset, and any downstream partners will feel the fallout.
Actionable takeaways for independent providers
First, do a hard‑nosed TCO analysis before you chase wafer‑scale hype. Factor in power, cooling, staffing, and support contracts for each hardware family. Second, consider whether you truly need Cerebras speed – most workloads still run fine on modern GPUs and CPUs. If you do need it, look for a partnership model that spreads the capital risk, similar to General Compute’s “we buy, you lease” approach.
Third, lock in flexible power contracts. The 15 MW option cited in the whitepaper is a good benchmark; if you can’t secure comparable capacity at a reasonable rate, the economics won’t work. Finally, keep an eye on the hyperscaler‑driven price war. As Nvidia, AMD, and even Cerebras push pricing down, the margin on premium inference services will shrink. Your competitive edge will have to come from operational excellence and niche expertise, not from riding the latest hardware hype.
— Allan Ali, Founder
This article was produced with AI-assisted research and editorial support. Reporting is based on the source material cited below. Sources: Data Center Dynamics; datacenterdynamics.com; Global1.News (04 October 2026).
By Allan Ali, Global1.News
What's Your Reaction?
 Like
0
 Dislike
0
 Love
0
 Funny
0
 Wow
0
 Sad
0
 Angry
0
Publisher of Global1.News. Automation architect, systems builder, and the guy making sure the truth gets published.








Comments (0)