
AI inference is running into a memory bottleneck. Huawei wants to tackle it with OceanStor M900
Huawei’s latest splash at HUAWEI CONNECT 2026 is the OceanStor M900 Context Memory Storage – a piece of kit that claims to slide the key‑value cache out of the cramped lanes of GPU and system RAM and into a shared storage tier.
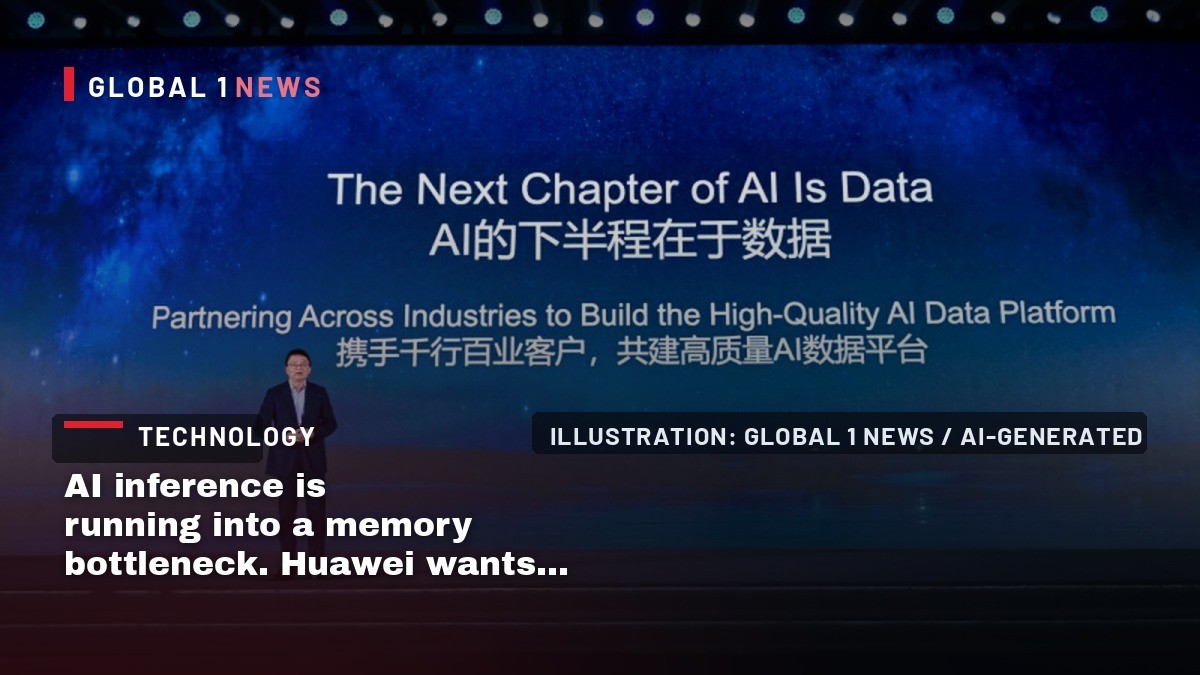
Huawei’s latest splash at HUAWEI CONNECT 2026 is the OceanStor M900 Context Memory Storage – a piece of kit that claims to slide the key‑value cache out of the cramped lanes of GPU and system RAM and into a shared storage tier. For anyone running production AI inference, the promise is seductive: more context per NPU, lower latency, and a claim of halving the time to first token on coding workloads. But the hype needs to be weighed against the hard realities of running AI services at scale, especially for independent hosting providers that can’t afford to hand over their cash to hyperscaler‑style pricing.
Why the KV cache is the new choke point
The Register’s piece makes it clear that the KV cache – the structure that lets a model reuse prior computations – is exploding as context windows grow. Multi‑turn conversations and agentic workloads mean the cache can no longer be a tiny, fast‑access slab sitting in GPU memory. When the cache outgrows the fast tier, the accelerator stalls, waiting for data that sits in slower system RAM or, worse, on traditional SSDs.
That latency penalty is not just a few microseconds; it translates into noticeable slow‑downs in token throughput and higher costs per inference. For a hosting provider, every millisecond of idle accelerator time is a missed revenue opportunity. The industry’s current “just add more GPU RAM” playbook quickly hits a wall – GPU memory is expensive, and capacity is finite.
Huawei’s answer: a dedicated context memory layer
Huawei’s OceanStor M900 is pitched as a “dedicated Context Memory Storage layer” that sits between the compute and the bulk storage. By extending the KV cache into a multi‑tier pool, it promises to keep more of the cache close to the NPU without blowing up the cost of GPU memory. The platform uses Huawei’s UnifiedBus interconnect, which the vendor says lets a cluster share KV resources and reach a capacity of up to 64 PB.
In practice, that means a provider could offload part of the KV cache to this storage tier and still serve inference requests without the accelerator sitting idle. The claim of “substantially more context per NPU” is attractive, but the real test will be whether the latency of the storage tier truly stays in the microsecond range when you scale out to dozens of nodes.
Latency claims versus production realities
Huawei touts a 60‑microsecond access latency for the OceanStor M900, saying it can double token throughput and cut the time to first token in typical AI coding workloads. On paper, that sounds like a game‑changer. However, the figure is measured under ideal conditions – a single hop from NPU to the ASU disk, bypassing conventional protocol conversion and CPU forwarding.
In a real‑world data centre, you have to factor in network congestion, queueing on the UnifiedBus, and the overhead of KV‑aware placement logic. Independent operators often see latency spikes when a storage node is under heavy load, and the “single hop” advantage can evaporate if the storage controller becomes a bottleneck. The claim is promising, but it needs validation in a production environment where traffic is bursty and workloads are heterogeneous.
Cost and durability: more than a marketing line
The Register notes that Huawei’s KV‑aware adaptive storage technology manages data placement based on cache lifecycles, with an endurance of up to 24 drive writes per day – roughly sixteen times that of conventional SSDs. If true, that could translate into lower replacement cycles and reduced maintenance overhead. For a hosting firm that already battles high SSD churn rates, a longer‑lasting drive can be a real cost saver.
But durability alone doesn’t solve the economics. The storage tier still needs to be purchased, powered, and cooled. Huawei positions the M900 as a way to reduce “replacement and maintenance costs over time,” yet the upfront CAPEX for a 64 PB‑scale system is non‑trivial. Smaller providers will have to decide whether the operational savings offset the initial outlay, especially when hyperscalers can amortise such costs across massive fleets.
The broader shift: merging memory, networking and compute
Huawei’s narrative is that storage should no longer be a peripheral support component but an integral part of the inference pipeline. By embedding CPU, networking and storage controller functions into the ASU disk, they aim to collapse the data path to a single hop. This reflects a wider industry trend where memory, networking and compute are converging – think of NVIDIA’s DGX‑H and AMD’s Infinity Fabric.
For independent operators, this convergence is a double‑edged sword. On one hand, tighter integration can shave latency and simplify stack management. On the other, it locks you into a vendor’s ecosystem, reducing flexibility. If you’re already juggling multiple hardware vendors, adding a proprietary storage layer could increase complexity rather than reduce it.
Risk assessment for independent hosting providers
The key question is risk versus reward. The M900 promises to alleviate the KV cache bottleneck, but it also introduces a new dependency on Huawei’s UnifiedBus and ASU technology. Should there be a firmware bug or a supply‑chain hiccup, you could lose a critical tier of your inference pipeline. Moreover, the “shared, multi‑tier storage pool” model means that a failure in one node could ripple across the cluster, affecting all customers.
From a business‑risk perspective, you need to evaluate the maturity of the platform, the availability of support contracts, and the ability to fall back to a more conventional storage hierarchy if needed. Diversifying across vendors – keeping a portion of the KV cache in GPU RAM and a portion on a proven SSD tier – can hedge against a single‑point‑of‑failure scenario.
Actionable steps for founders and operators
First, benchmark your current KV cache utilisation. If you’re already hitting memory limits on your GPUs, the M900’s extended tier could be worth a pilot. Second, run latency tests with a realistic workload – include bursty traffic and multi‑node inference – to see if the 60‑microsecond claim holds up under load. Third, calculate total cost of ownership: factor in hardware cost, power, cooling, and expected drive lifespan versus your existing SSD churn rate.
Finally, consider a hybrid approach. Keep the hotest cache in GPU memory, offload the warm tier to a high‑performance SSD array you already own, and use the M900 (or a similar solution) as an optional overflow for the longest context windows. This lets you reap some latency benefits without fully committing to a single vendor’s stack.
In short, Huawei’s OceanStor M900 is an intriguing answer to the memory bottleneck that’s choking AI inference today. It offers a technically elegant solution – a dedicated context memory layer with microsecond latency and high endurance – but the real test will be whether independent providers can justify the cost, manage the risk, and actually see the promised throughput gains in production. As always, the devil’s in the details, and the only way to know is to put it through the gauntlet of a real‑world workload.
— Allan Ali, Founder
This article was produced with AI-assisted research and editorial support. Reporting is based on the source material cited below. Sources: The Register; theregister.com; Global1.News (21 October 2026).
By Allan Ali, Global1.News
What's Your Reaction?
 Like
0
 Dislike
0
 Love
0
 Funny
0
 Wow
0
 Sad
0
 Angry
0
Publisher of Global1.News. Automation architect, systems builder, and the guy making sure the truth gets published.







Comments (0)