
Bland Launches Tofu-1, a Full-Duplex Speech-to-Speech Model for Calls
When Bland rolled out its Tofu‑1 model last week, the buzz in the AI press was all about “full‑duplex speech‑to‑speech” and the fancy TV Test. The company lists three “audio skills”: speaker tracking, noise separation and paralinguistics.
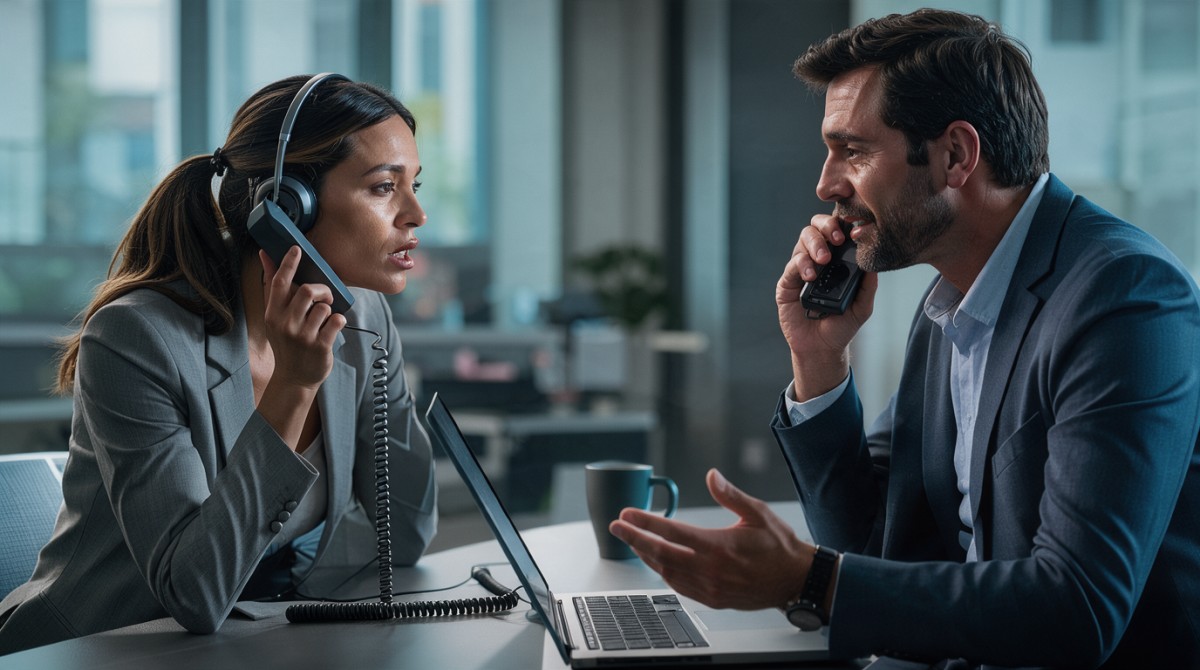
When Bland rolled out its Tofu‑1 model last week, the buzz in the AI press was all about “full‑duplex speech‑to‑speech” and the fancy TV Test. As someone who’s been wiring up real phone‑agent infrastructure for a decade, I’m less interested in the hype and more in what this actually means for the trenches of call‑center ops and the independent hosting outfits that keep them humming. Bland’s claim that Tofu‑1 can listen, reason and reply in audio without ever converting to text is a neat technical trick, but the real question is whether it delivers a tangible cost or risk advantage over the cascade pipelines that dominate today’s production stacks.
What Tofu‑1 Actually Does
At its core, Tofu‑1 is a full‑duplex speech‑to‑speech model that processes inbound audio while simultaneously generating outbound audio. Unlike the typical cascade—where speech is transcribed, fed to a language model, then re‑synthesized—Bland says its model keeps the raw waveform in play, preserving tone, hesitation and background ambience. The company lists three “audio skills”: speaker tracking, noise separation and paralinguistics. In practice, that means the model can tell who’s talking, filter out a crying child or a TV blaring in the background, and pick up on frustration or urgency in the caller’s voice.
Another touted feature is the ability for callers to interrupt mid‑sentence. The model continues working on the request while the conversation rolls on, only reporting completion when the task is truly done. This “thinking while talking” approach is designed to keep the dialogue fluid, avoiding the dead air that often plagues traditional voice agents waiting for a transcript‑based response.
Why Full‑Duplex Matters for Noisy Environments
Bland positions Tofu‑1 for “calls from moving cars, hospital rooms and weak‑signal lines.” Those are exactly the scenarios where cascade pipelines stumble. When you’re on a shaky cellular link, the transcription engine can mis‑hear, leading to garbled intents and costly retries. By staying in the audio domain, Tofu‑1 can theoretically leverage background cues—like the rumble of a car or the beeping of medical equipment—to better understand context without the error‑prone transcription step.
The TV Test, a demo where the model must follow a caller while a louder TV plays in the background, illustrates this point. Bland admits the walkthrough is illustrative, not a recorded output, but the premise is clear: if the model can ignore a louder, irrelevant audio source, it could reduce false triggers that plague current voice assistants in noisy settings.
How It Stacks Up Against the Competition
The press release includes a sparse comparison table. While OpenAI’s GPT‑Live‑1 and NVIDIA’s NemotronLabs VoiceChat also claim full‑duplex capabilities, the only concrete metric we have is latency for the latter—around 448 ms on its benchmark. Bland does not disclose Tofu‑1’s turn‑taking latency, nor its parameter count, leaving a blind spot for anyone trying to benchmark performance. The lack of open weights (Bland’s are closed) further limits independent verification.
What’s notable is that competitors are offering open or at least more transparent models, whereas Bland keeps the model behind a research‑preview API. For enterprises, that means you’re locked into Bland‑hosted hardware—A100, H100, H200, B100, B200, or RTX‑6000—without the option to run the model on your own servers. That’s a red flag for anyone wary of vendor lock‑in, especially when you factor in the cost premium that hyperscalers typically charge for proprietary AI services.
Enterprise Access and Pricing Mystery
Access to Tofu‑1 is limited to a “research preview” for a handful of enterprises in banking, healthcare, insurance and government. The sign‑up form asks for monthly call volume ranging from under 1,000 to 50,000+. Bland has not published any pricing, and the lack of a public pricing tier makes it impossible to run a cost‑benefit analysis. In my experience, when a vendor withholds pricing, they’re either testing the waters or planning to charge a premium that reflects the “first‑to‑market” advantage.
For independent hosting providers, this opacity is a deal‑breaker. You need to know the per‑call or per‑minute cost to decide whether to integrate Tofu‑1 into a SaaS offering or to stick with open‑source cascade pipelines that can be run on commodity GPU farms. Until Bland releases a transparent pricing sheet, the risk of an unexpected bill looms large for any startup looking to adopt the model.
Operational Risks and Real‑World Deployment
From a production standpoint, the promise of “no transcript” is appealing, but it also removes a useful debugging layer. With cascade systems, you can inspect the transcript to see where the model went off‑track. Full‑duplex audio‑only pipelines give you only the final audio output, making it harder to pinpoint errors in the reasoning chain. That could translate into longer mean‑time‑to‑repair (MTTR) when something goes wrong in a live call center.
Moreover, the model’s ability to generate synthetic call audio—including a second speaker, room ambience and line noise—opens up potential misuse. If you can synthesize a realistic call, you also need robust detection mechanisms to prevent fraud or deep‑fake attacks. Hosting providers must factor in the security overhead of monitoring for synthetic audio abuse, a cost that isn’t reflected in any disclosed pricing.
Strategic Takeaways for Hosting Founders
Bottom line: Tofu‑1 is an intriguing technical showcase, but it’s not a turnkey solution for most independent operators. The lack of disclosed latency, parameter size, pricing and open weights means you’re betting on a black‑box service that could lock you into Bland’s infrastructure. If you run a call‑center platform and your primary pain point is noisy environments, you might experiment with the research preview on a small pilot, but you should keep a fallback cascade pipeline ready.
My advice for founders is threefold: first, run a controlled A/B test comparing Tofu‑1 against your existing transcription‑based stack on a subset of noisy calls; second, negotiate clear SLAs around latency, uptime and cost before committing to any long‑term contract; third, build observability into the audio pipeline so you can surface audio cues (like speaker tracking confidence) for troubleshooting. Until Bland opens up the model or offers transparent pricing, the prudent move is to treat Tofu‑1 as a research curiosity rather than a production workhorse.
Looking Ahead: The Future of Full‑Duplex Voice AI
The launch of Tofu‑1 signals that the AI community is serious about moving beyond text‑centric pipelines. If the technology matures and vendors start offering open weights or at least clearer performance metrics, we could see a shift toward audio‑first agents that handle calls in real time without the transcription bottleneck. That would be a game‑changer for sectors like telemedicine and on‑road logistics, where every second counts and background noise is the norm.
For now, though, the industry is still in the early‑adopter phase. Independent hosting providers should keep an eye on the evolution of full‑duplex models, but remain cautious about vendor lock‑in and hidden costs. The real value will emerge when the models are benchmarked on standard latency tests, priced transparently, and made runnable on third‑party hardware. Until then, stick to what you know works, and treat Tofu‑1 as a promising but unproven experiment.
— Allan Ali, Founder
This article was produced with AI-assisted research and editorial support. Reporting is based on the source material cited below. Sources: MarkTechPost; marktechpost.com; Global1.News (17 November 2026).
By Allan Ali, Global1.News
What's Your Reaction?
 Like
0
 Dislike
0
 Love
0
 Funny
0
 Wow
0
 Sad
0
 Angry
0
Publisher of Global1.News. Automation architect, systems builder, and the guy making sure the truth gets published.







Comments (0)