
Marvell and Penguin Solutions aim to end the RAMpocalypse with photonic memory fabric
Marvell and Penguin Solutions just dropped a photonic memory fabric that promises to shift the whole memory‑to‑compute paradigm. As a founder who’s been wiring up racks for a decade, I can smell both opportunity and hype.
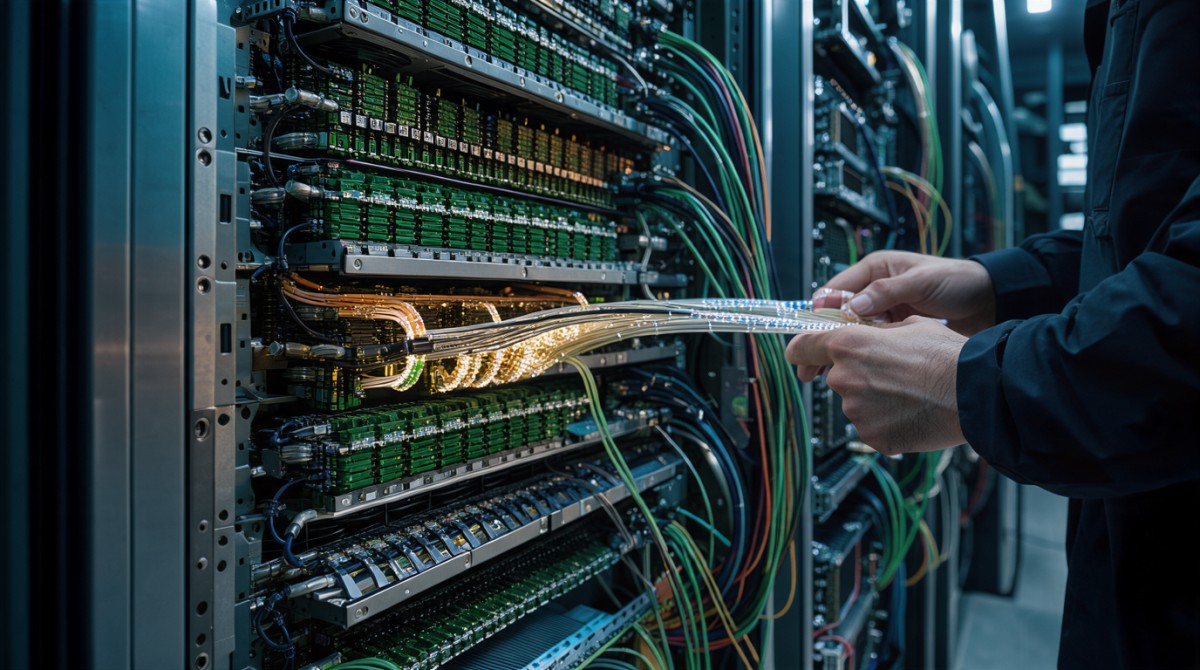
Marvell and Penguin Solutions just dropped a photonic memory fabric that promises to shift the whole memory‑to‑compute paradigm. As a founder who’s been wiring up racks for a decade, I can smell both opportunity and hype. The tech basically lets you pool DRAM and a slice of HBM across a handful of servers, cutting the need for each box to carry its own massive DRAM bank. On paper, that sounds like a win for AI workloads choking on memory, but the devil is in the deployment details and the price tag that sits behind the scenes.
What the hardware actually is
The core of the offering is a memory expansion module that stacks two HBM3e dies for a total of 72 GB and adds eight DDR5 channels on a silicon photonic interposer. The interposer can push 7.2 Tbps (roughly 900 GB/s) of bidirectional bandwidth. Marvell supplies these modules; Penguin builds the enclosure, handles power, software and the management stack.
Penguin’s first generation will house 16 of those modules, delivering up to 16 TB of DDR5 and 1 TB of HBM to a cluster of up to 16 servers. Future versions could double the DDR5 capacity. Bandwidth is distributed via a Marvell‑designed optical fiber shuffle that can move 57.6 Tbps across the appliance, feeding the attached servers through a NIC, a co‑packaged (CPO) module, or a near‑packaged optical (NPO) module.
Why the photonic angle matters
Optical interconnects are the only way to keep latency low and bandwidth high when you start moving memory off the board. The 7.2 Tbps per module and the aggregate 57.6 Tbps fabric are impressive numbers, but they only matter if you can actually get that throughput to the CPU or GPU without a costly redesign. That’s where CPO and NPO come in. CPO plugs directly into the compute ASIC – think of it as a memory‑sidecar that lives on the same silicon. NPO, on the other hand, sits electrically on the host and hands the rest of the data off to the photonic fabric.
Penguin is betting that NPO will be the sweet spot for the next wave of rack‑scale systems from Nvidia and AMD. It offers better serviceability and a lower blast radius than embedding photonic chiplets straight into the CPU or GPU, a practical concern when you’re trying to keep uptime high in a production environment.
The software glue – and why it matters to us
Penguin has built a software layer that presents the pooled memory as a single address space, much like a network‑attached storage share. The layer can be accessed via CXL 3.1‑compatible NICs and CPUs – for example, AMD’s Venice line – but according to Marvell’s senior VP Preet Virk, the CXL stack can be bypassed entirely for CPO and NPO configurations. Bypassing CXL could shave latency, but it also means you’re tying yourself to a proprietary stack that may not play nicely with other vendors.
The software also supports tiering modes that mirror typical CXL memory tiering, with a twist: an HBM cache‑through mode that treats the 1 TB of HBM as a read/write cache in front of the DDR5. Frequently accessed data hits the HBM first, then drifts into DDR5 as it ages. In theory, that gives you the speed of HBM with the capacity of DDR5, a useful trick for AI inference where large key‑value (KV) caches dominate memory use.
AI workloads and the KV cache angle
Marvell frames the appliance as an alternative to offloading KV caches to storage. In large language model inference, each chat session builds a KV cache that can run into gigabytes. Those caches are expensive to recompute and costly to keep in DRAM for long‑running agents. The current practice is to spill inactive caches to DRAM or flash, which is faster than recompute but still a bandwidth hog.
By moving KV caches onto the photonic fabric – specifically into the HBM cache‑through tier – you could keep hot entries in ultra‑fast memory while the rest sits in DDR5. Marvell claims this improves performance and utilization, and it mirrors what Meta has already done in its own datacenters, where pooled memory reduces per‑node DRAM footprints.
Business risk: cost versus benefit
The first red flag for any independent hosting provider is cost. Marvell paid $3.5 billion for the underlying tech from Celestial AI. While the article doesn’t disclose pricing for the appliances, the sheer scale of the acquisition suggests a premium product. For a boutique provider, the capital outlay to buy a 16‑node fabric and integrate it into existing racks could be prohibitive.
Even if the hardware cost can be amortized, you have to consider the operational complexity. Managing a shared memory pool across 16 servers adds a new layer of failure domains. The optical fiber shuffle, while fast, introduces additional points of failure – connectors, transceivers, and the firmware that orchestrates the fabric. If the software layer misbehaves, you could see memory stalls that ripple across all attached workloads.
Practical deployment scenarios
For providers focused on AI inference services, the fabric could shave the DRAM per node by a noticeable margin, especially if you can lean on the HBM cache‑through mode for hot KV caches. That translates into lower power draw per server and potentially higher density in a rack. However, you’ll need to redesign your server chassis to accommodate the NIC or CPO/NPO modules, and you’ll have to train ops staff on the new optical interconnects.
For more general‑purpose hosting, the benefit is less clear. Most web workloads still fit comfortably within a few hundred gigabytes of DRAM per rack. Adding a photonic fabric may be overkill unless you’re running large‑scale AI services or high‑performance computing workloads that truly need the extra bandwidth.
Actionable advice for founders
If you’re considering the Marvell‑Penguin fabric, start with a clear ROI model. Map out how much DRAM you can safely trim from each node and translate that into power and hardware savings. Then factor in the upfront cost of the appliance, the integration effort for CPO/NPO modules, and the ongoing support overhead for the proprietary software stack.
Run a pilot on a non‑production cluster. Use it to stress‑test the HBM cache‑through tier with real KV cache workloads – that’s the sweet spot the vendors are selling. Monitor latency, error rates, and the impact on overall job completion times. If the pilot shows a measurable performance lift without destabilising your environment, you have a case to roll it out more broadly.
Finally, keep an eye on the broader ecosystem. The photonic fabric leans on CXL 3.1 today, but the vendors claim you can bypass it. If the industry settles on an open standard for pooled memory, you might avoid vendor lock‑in by waiting for a more interoperable solution. Until then, treat this as a high‑risk, high‑potential‑reward experiment rather than a plug‑and‑play upgrade.
— Allan Ali, Founder
This article was produced with AI-assisted research and editorial support. Reporting is based on the source material cited below. Sources: The Register; theregister.com; Global1.News (16 November 2026).
By Allan Ali, Global1.News
What's Your Reaction?
 Like
0
 Dislike
0
 Love
0
 Funny
0
 Wow
0
 Sad
0
 Angry
0
Publisher of Global1.News. Automation architect, systems builder, and the guy making sure the truth gets published.







Comments (0)